AIFuture
Back to news
IndustryThe Decoder·

Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated
Nvidia says its Groq 3 LPX is four times faster than Cerebras, but the math is more complicated

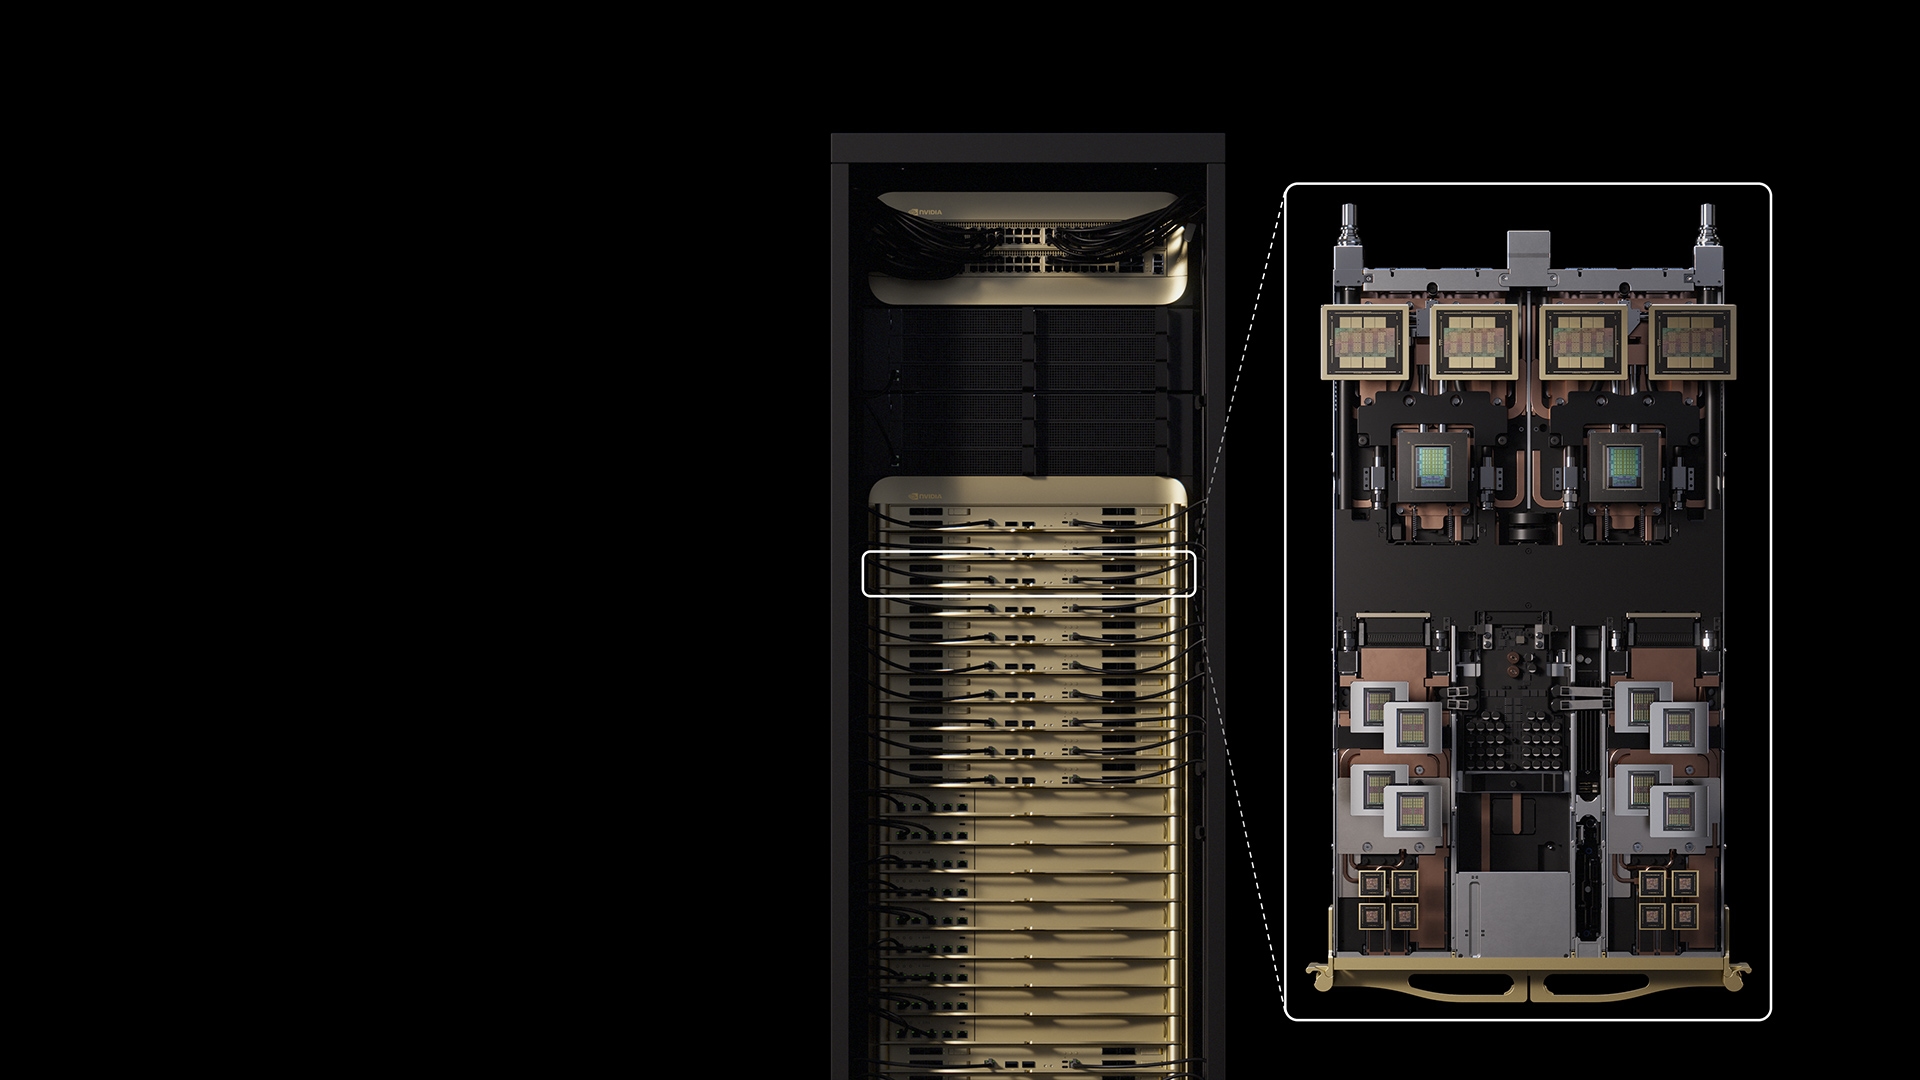
Nvidia is moving its Groq 3 LPX inference chip into full production and reports 3,400 tokens per second on Gemma 4 31B, four times faster than Cerebras. But the numbers don't tell the whole story. Nvidia needs at least 64 accelerators to get there, while Cerebras needs only one or two, according to The Register. How well the architecture scales with large MoE models remains an open question. The…

This is a summary curated by AIFuture. Read the complete article at the original source:

Read the full story on The Decoder

Build the skills behind the headlines

Generative AICoursera

Generative AI for Everyone

Andrew Ng explains how generative AI works and how to apply it in your work and life — no coding required.

Beginner·Subscription
View Course
Data ScienceCoursera

Deep Learning Specialization

Five-course series on neural networks, CNNs, sequence models, and transformers from DeepLearning.AI.

Intermediate·Subscription
View Course
Data ScienceCoursera

Machine Learning Specialization

Andrew Ng's flagship program covering supervised and unsupervised learning, neural networks, and best practices for real-world ML.

Beginner·Subscription
View Course

Never miss what matters in AI

Get the most important AI news and course picks in your inbox.